WorldOracle launches first real-execution benchmark for world models
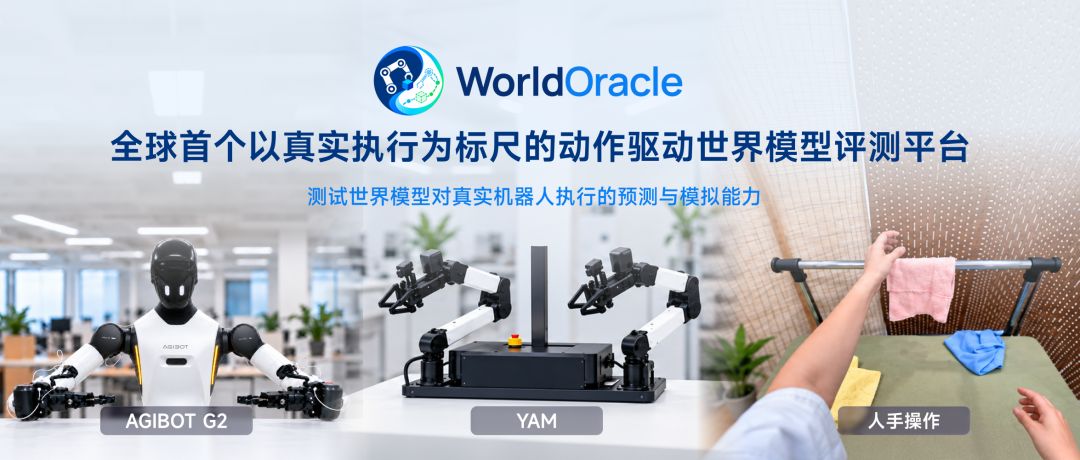
AgiBot, NVIDIA, Princeton, UT Austin and Toronto launched WorldOracle, a benchmark that grades world models against real-world execution.
A research team spanning AgiBot, NVIDIA, Princeton University, the University of Texas at Austin and the University of Toronto has launched what it describes as the first benchmark for action-driven world models that uses real-world execution as the yardstick. WorldOracle opened on October 16 with a public leaderboard and open evaluation submissions.
The benchmark asks a question the field has lacked a direct way to answer: given a set of actions, how far is the model’s predicted future from what actually happens? The team calls this “Execution Coherence” and tests it under three stresses — causal obedience (follow the given action sequence, including wrong or failed operations), distribution shift (handle teleoperated and autonomous-policy actions with pauses, jitter and corrections) and temporal endurance (keep errors controlled after 120 seconds of continuous operation, not just the first 10).
The evaluation set holds 335 trajectories of about two minutes each: 100 from the AgiBot G2 robot, 75 from the YAM robot, 100 from first-person human hand operation and 60 from policy-autonomous execution. Crucially, about 40 percent of the interaction clips are failures or suboptimal executions — missed grasps, drops, spilled water — preserved so that accurately predicting a failure earns a high score. Tasks cover fruit grasping, towel hanging, water pouring and drawer operation.
The first results are sobering for the world-model boom. The team evaluated seven representative models — IRASim, Ctrl-World, DreamDojo, Cosmos 3, GE-Sim 2.0, JointControlVideo and OSCAR — and found they replicate arm motion while missing what the motion does to the world: on G2 human-operated trajectories, even the strongest model scored 100.0 on the arm but only 62.8 on the manipulated object. Long-horizon scores collapsed across the board, and human hands remain a blind spot, with the best zero-shot model reaching only 15.2 on object-region fidelity for hand scenarios.
The paper is published on arXiv (2610.18826) and the code is open at github.com/AgibotTech/WorldOracle. Submissions are open to open-weight and closed models after registration and review — the field’s next progress, the team argues, will be measured not by prettier predictions but by fewer misjudgments of what actually happens.